What happens in the Bandit AI video, shot by shot?
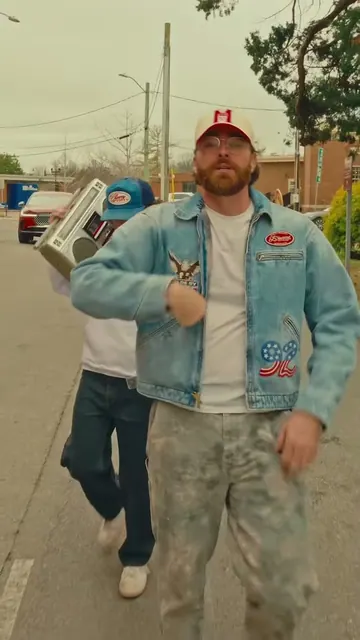
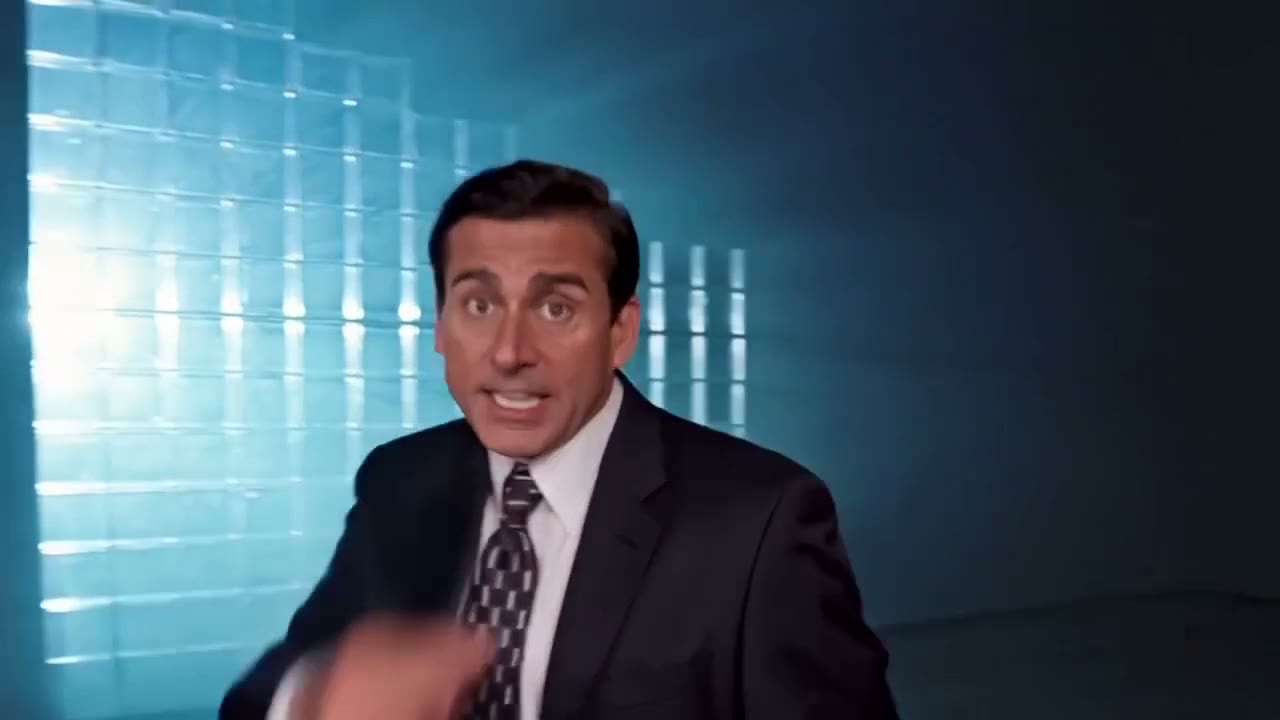
Duo copies the same 15 seconds of the Bandit music video that the trend sound uses, cut for cut. Photo 1 (you) takes the lead rapper's place, photo 2 (your friend) the partner's; the sets, the camera and the moves stay:
| Time | What you see |
|---|---|
| 0 to 2.2 s | A night lawn under a bright floodlight: you walk toward the camera and rap in a red, white and blue racing jacket. Your friend steps in next to you; quad bikes and dirt bikes roll behind. |
| 2.2 to 4.7 s | A dark studio with tall glowing blue light bars: you rap to the camera while it pushes in. |
| 4.7 to 5.6 s | The two of you turn into gold hand-drawn line drawings. |
| 5.6 to 7.4 s | A rider pops a wheelie on a green quad bike. |
| 7.4 to 9.7 s | In front of a low wall at night, you rap and wave a hand at the camera. |
| 9.7 to 12.6 s | A field of tall golden grass: you rap in a white racing jacket as the camera moves in to a close-up. |
| 12.6 to 15 s | Back in the blue studio, a close-up of you rapping straight into the lens. |
How it works: top-quality AI video models, including Seedance 2.5, edit the clip itself and put each face from your photos into every shot of its rapper. You get about 15 seconds at 720p, wide 16:9 like the music video, with the song put back on after the run. You can turn the sound off on the result screen. The mouths follow the rap in the clip, so they look close to the words, but it is not exact lip sync. A run takes 5 to 15 minutes, and the exact price shows on the Generate button before you spend anything. Every run is a new take, so results differ.