
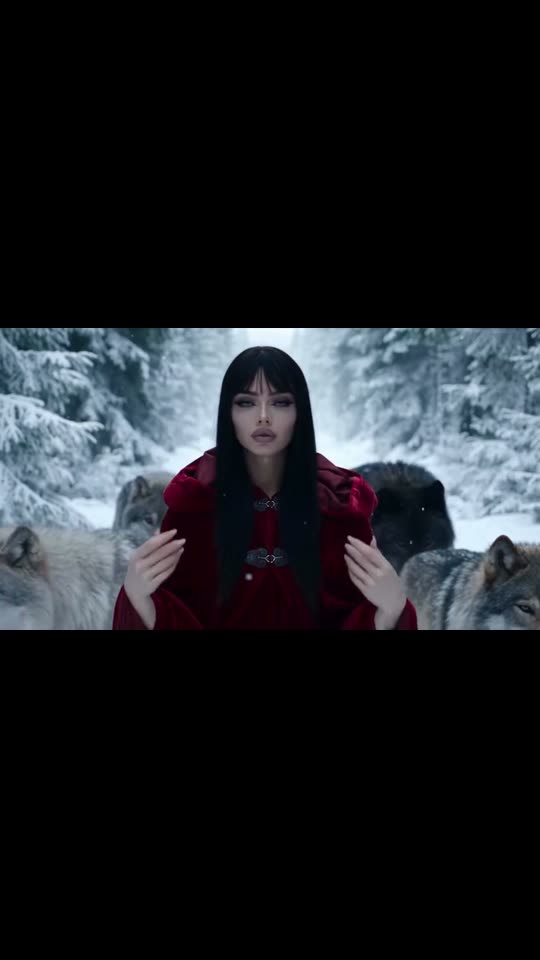
What happens in the AI Red Riding Hood video, second by second?
Your video copies the reel's first seven shots, about 15 seconds, with the same cuts and the same slow camera. Only the figure in the red cloak changes:
| Time | Shot | Human | Pet |
|---|---|---|---|
| 0 to 2.5 s | A very wide shot down a snowy road between tall pines | A tiny red figure far away walks toward the camera | A tiny red speck, your pet, comes down the road |
| 2.5 to 7.2 s | Three wider shots, the wolves walk alongside | You walk toward the camera, hood up, grey wolves at your side | Your pet trots through the snow in its red cape, between the much bigger wolves |
| 7.2 to 8.5 s | Medium shot | You stop, the face still in the shadow of the hood | Your pet stops, the hood over its head |
| 8.5 to 13 s | Close-up, the reveal | You lower the hood with both hands and look up into the lens | The hood slips back and your pet looks up into the lens |
| 13 to 15 s | Medium shot | You stand calm, the wolves around you | Your pet sits calm among the wolves |
How it works: the best AI video models available, including Seedance 2.5, edit the reel itself: they put the person or pet from your photo in the red cloak and keep the forest, the wolves, the snow and the camera. You get about 15 seconds at 720p, wide 16:9 like the reel, with the reel's slowed song put back after the run. A run takes 5 to 15 minutes, and the exact price shows on the Generate button before you spend anything. Every run is a new take, so results differ.
Why is it wide and not vertical? The reel is wide, and the wolves walk on both sides of the figure. A vertical crop would cut most of the pack out of the walking shots and lose the look, so the template keeps the wide frame. It still plays on TikTok, Reels and Shorts.